OpenAI has announced local processing and inference for its API in India, giving eligible businesses and developers a way to keep supported AI workloads inside the country. Announced on November 12, 2026, the move extends OpenAI’s existing India data residency option — which previously covered where customer content is stored — to where the model actually processes that content and generates its response. At launch, the capability covers OpenAI’s GPT-6 Luna model through the Responses and Chat Completions APIs.
For India’s regulated industries, the distinction matters. Storing data in-country while sending it abroad for every model call was always a half-measure for banks, insurers and healthcare providers with localisation requirements. With inference residency, both the API request intake and the model computation that produces the response now take place in India for supported workloads — a change that could move more Indian enterprises from AI experiments to production deployments.
What OpenAI Announced
OpenAI introduced API inference residency in India on November 12, 2026, as part of a wider regional expansion that also adds Australia and Japan. The offering is aimed squarely at enterprises and developers using the OpenAI API directly, not at regular ChatGPT app users — the consumer experience is unchanged.
For supported workloads, the promise is straightforward: the API request is processed in India, the model computation that generates the response happens in India, and supported customer content is stored in India. The initial scope is deliberately narrow — GPT-6 Luna only, direct API usage only, through the Responses API and the Chat Completions API. Nitin Bawankule, OpenAI’s Head of Enterprise for India, said local inference gives businesses greater control over where their data is processed and could help more organisations move from experimenting with AI to using it in day-to-day operations.
From Data Residency to Inference Residency
Data residency and inference residency sound similar, but they cover different parts of an AI workload. Data residency answers one question: where is my data stored at rest? Inference residency answers a harder one: where does the computation happen?
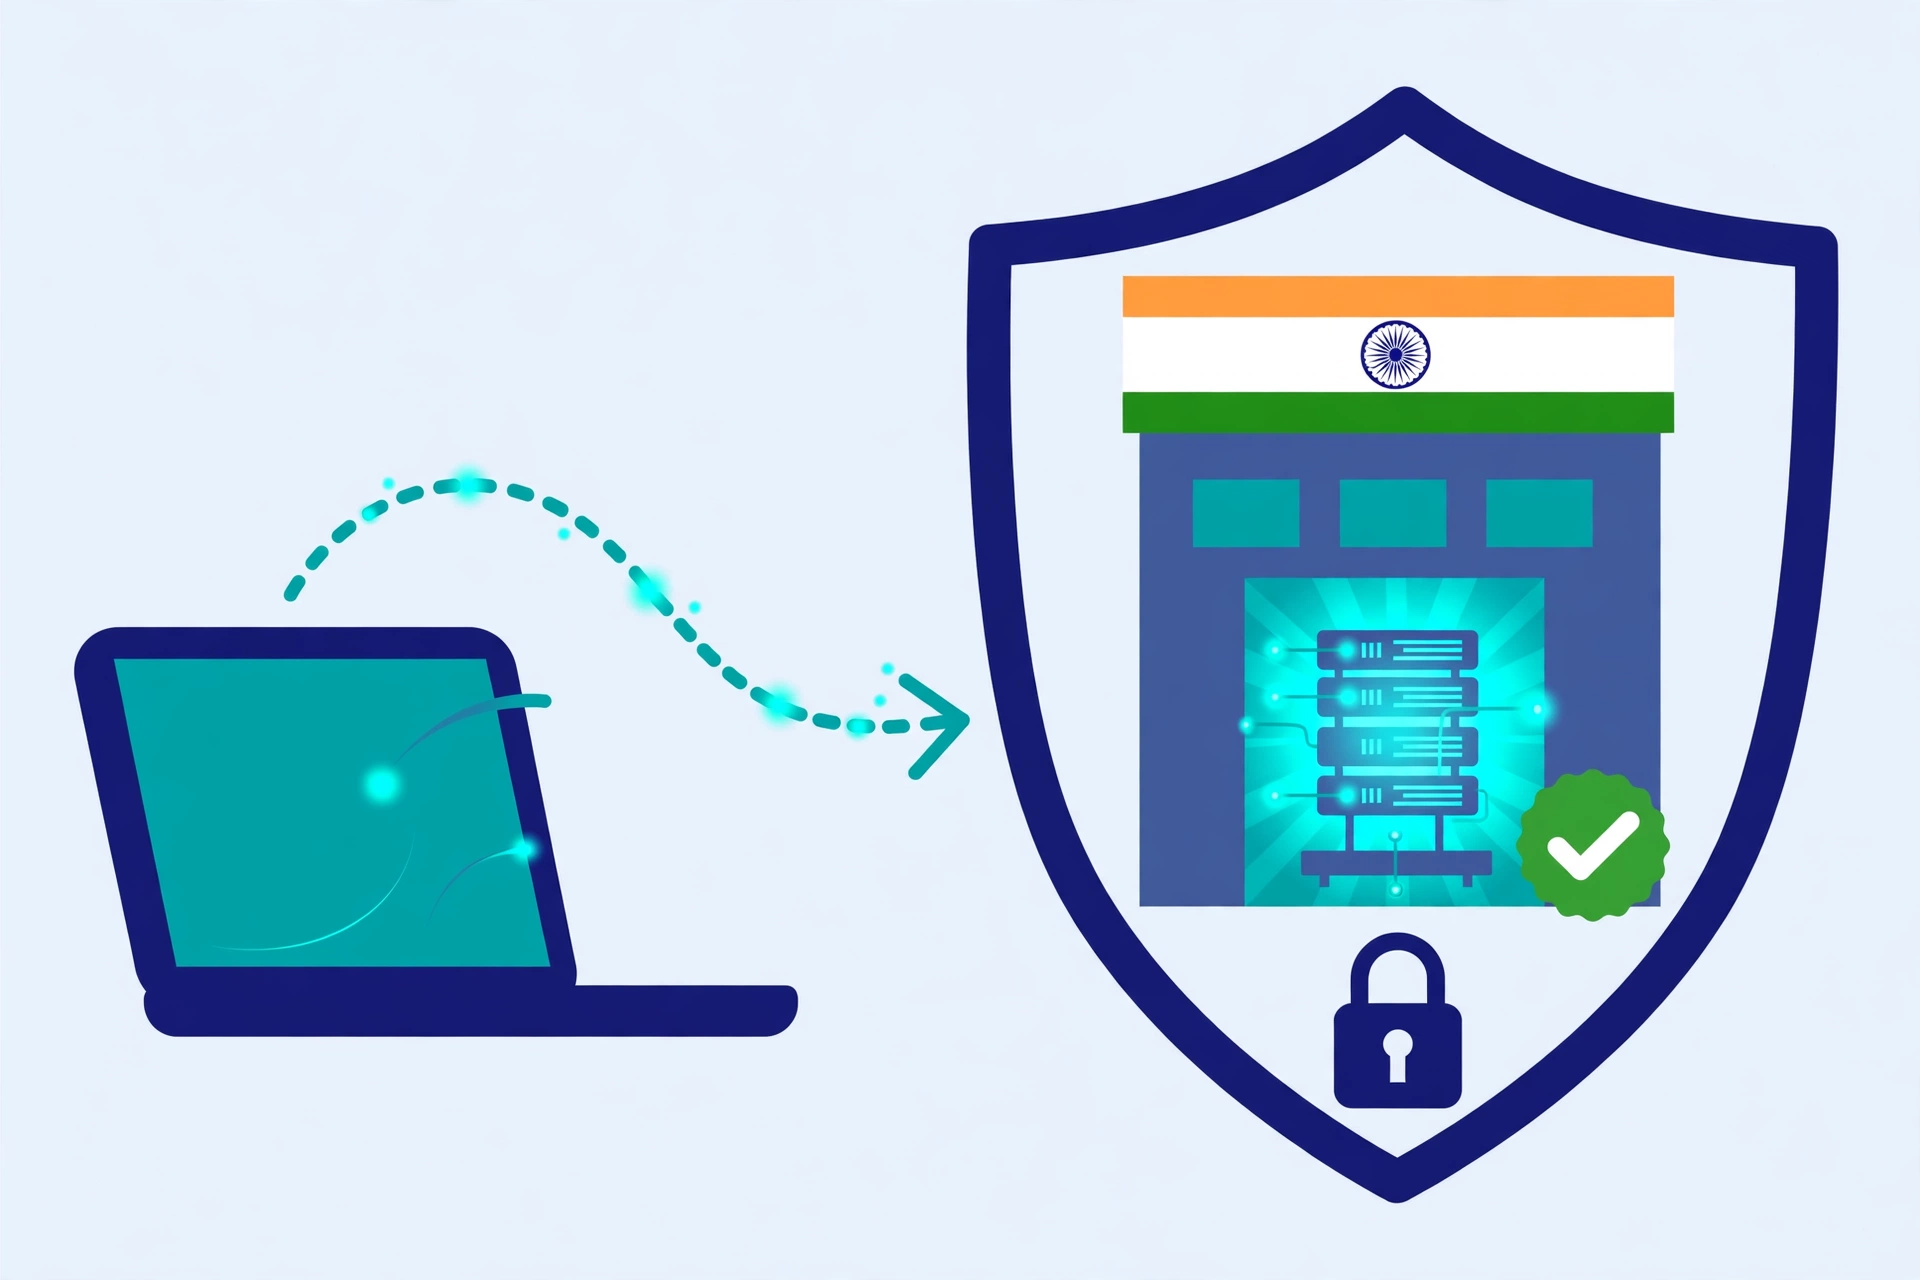
Until now, OpenAI’s India option covered storage. A bank could keep its customer content in India, but the moment it sent a document to GPT-6 Luna for analysis, the request and the model call could travel elsewhere. The new offering extends OpenAI’s data residency capabilities beyond storage to include processing, closing that gap for supported workloads. That matters for use cases like document analysis, automated drafting and data synthesis, where the payload itself is the sensitive asset.
The distinction is also what separates OpenAI’s move from a simple region launch. Inference residency is a compliance feature, not a performance one — although local processing can reduce latency, the headline benefit is control: organisations in regulated sectors can show auditors and regulators exactly where their AI processing happens, rather than relying on storage-location promises alone.
Who Can Use It — and What It Takes
Access is not automatic. According to OpenAI’s API documentation, as reported in coverage of the launch, organisations need active Zero Data Retention (ZDR) — subject to OpenAI approval — to use regional processing in India. Modified Abuse Monitoring alone is not sufficient.
Eligible customers must create a new regional API project, select India as the location for both data storage and processing, and route supported requests through the corresponding regional India endpoint. The India region currently supports only Standard pay-as-you-go processing, and DQ India reports a 10% premium for GPT-6 Luna regional processing. OpenAI-hosted tools are unavailable for regional processing in India at launch.
The ZDR requirement is the real gate. Zero Data Retention means OpenAI does not retain the content of API requests for training or other purposes — a condition many regulated enterprises already require. For teams that already run governed AI agents with strict data controls, the requirement will feel familiar; for everyone else, it is a compliance step to complete before the India endpoint becomes available.
What It Does Not Cover
The launch comes with clear boundaries, and OpenAI has been explicit about them:
- GPT-6 Luna only: No other model is covered at launch, and there is no announced date for adding more.
- Direct API usage only: The capability does not extend to ChatGPT or other OpenAI products.
- No hosted tools: OpenAI-hosted tools are not currently available for regional processing in India, Australia or Japan.
- Standard processing only: Other processing modes are not supported in the India region.
- Not a blanket guarantee: The residency commitment applies to the supported models, endpoints and customer content covered by OpenAI’s terms — it should not be read as a promise that every part of an organisation’s AI workflow stays in India.
That last point deserves emphasis. Inference residency is a defined, scoped commitment, not a national data border. Teams that combine GPT-6 Luna with other models, tools or services still need to map where each piece of their pipeline runs — the same discipline that applies to securing autonomous AI agents in production.
Why India, Why Now
India is OpenAI’s largest market by users, and the announcement builds on OpenAI for India, the initiative launched earlier this year covering AI infrastructure, enterprise adoption, skills development and local partnerships. The timing also reflects a broader shift: governments and regulators around the world are tightening expectations about where AI workloads run, and the vendors that can offer local processing have a real advantage in regulated sectors such as banking, financial services and insurance.
India joins Australia and Japan as the latest markets to receive API inference residency, with the US, Europe and the UAE already offering it. The pattern is familiar from the wider AI industry: as frontier models get more capable, the competition shifts from raw performance to deployment control. Google’s Gemini 4 Carbon, for example, is being pitched on long-horizon agentic work and cybersecurity — the same enterprise buyers OpenAI is courting with local processing.
What This Means for Indian Enterprises
For Indian enterprises, the practical impact depends on where they sit on the AI adoption curve. Organisations already running GPT-6 Luna workloads with localisation requirements — banks processing loan documents, insurers summarising claims, healthcare providers analysing records — can now keep the entire supported request lifecycle in-country. That removes one of the most common objections raised by compliance teams and could accelerate production rollouts that were previously stuck in review.
For teams building always-on AI coworkers or AI decision models on top of the OpenAI API, inference residency adds a deployment option rather than a new capability: the model is the same, but where it runs is now a choice. Startups and smaller developers should note the eligibility bar — ZDR approval, a new regional project and Standard pay-as-you-go pricing mean this is an enterprise-grade offering first, with broader access likely to follow if the rollout expands to more models.
The 10% regional processing premium, if it holds, is a small price for regulated buyers and a real consideration for cost-sensitive teams. Either way, the direction of travel is clear: local AI processing is becoming a standard expectation, not a special request.
How to Enable It
Eligible organisations can enable the capability in a few steps:
- Confirm your organisation has active Zero Data Retention approved by OpenAI.
- Create a new API project and select India as the region for both data storage and processing.
- Route supported GPT-6 Luna requests through the regional India endpoint, using the Responses or Chat Completions API.
- Verify that your workloads stay within the supported scope — GPT-6 Luna, direct API usage, Standard pay-as-you-go processing — and that no hosted tools are in the path.
Teams should also review OpenAI’s API documentation for the current list of eligible regions and limitations, since the supported scope is likely to change as the rollout expands.
Frequently Asked Questions
What is OpenAI API inference residency in India?
A new option, announced November 12, 2026, that lets eligible businesses and developers process supported GPT-6 Luna API workloads in India — both the API request and the model computation that generates the response take place in the country, and supported customer content is stored there.
Which model is supported at launch?
GPT-6 Luna only, through the Responses API and the Chat Completions API. Other models and hosted tools are not covered at launch.
What do I need to use it?
An organisation with active Zero Data Retention approved by OpenAI, plus a new regional API project with India selected for both storage and processing. Standard pay-as-you-go processing is the only supported mode in the India region.
Does it change ChatGPT?
No. The launch covers direct API usage only. Regular ChatGPT app users are unaffected.
Which other countries have API inference residency?
India joins Australia and Japan as the latest additions. The US, Europe and the UAE already offer it.
OpenAI’s India inference residency is a measured, compliance-first step rather than a sweeping launch — one model, two APIs, and a clear eligibility bar. But for the regulated enterprises it targets, that narrow scope is exactly the point: it gives them the one thing they could not get before, a supported way to run frontier AI entirely within India’s borders. If the rollout expands to more models, as seems likely, it could become the default way Indian enterprises deploy OpenAI’s API.