Europe’s biggest open AI model is now free to download. On October 29, 2026, French AI lab Mistral released the weights of Mistral Large 4 — nicknamed “Le Chonk” — a natively multimodal model with about 1 trillion parameters. Anyone can now download it, fine-tune it, and run it on their own hardware, three weeks after it first appeared as an API-only public preview on October 6.
The release is the largest open-weight frontier model yet from a Western lab, and it lands at a moment when governments and companies are asking hard questions about who controls the AI they depend on. Mistral trained Large 4 from scratch on 3,800 NVIDIA Grace Blackwell GPUs in its own European data centers, and it pitches the model squarely as a foundation for sovereign AI: organizations can host it themselves, audit its lineage, and keep their data inside their own walls.
For developers, the headline is simpler. The open-weight checkpoint is not a frozen copy of the preview — Mistral says three extra weeks of reinforcement learning brought large gains in coding, defensive cybersecurity, and reasoning efficiency. The company calls Large 4 the best open-weight model for coding, and the numbers it reports put it ahead of every other openly downloadable model on several coding benchmarks.
What Mistral Large 4 actually is
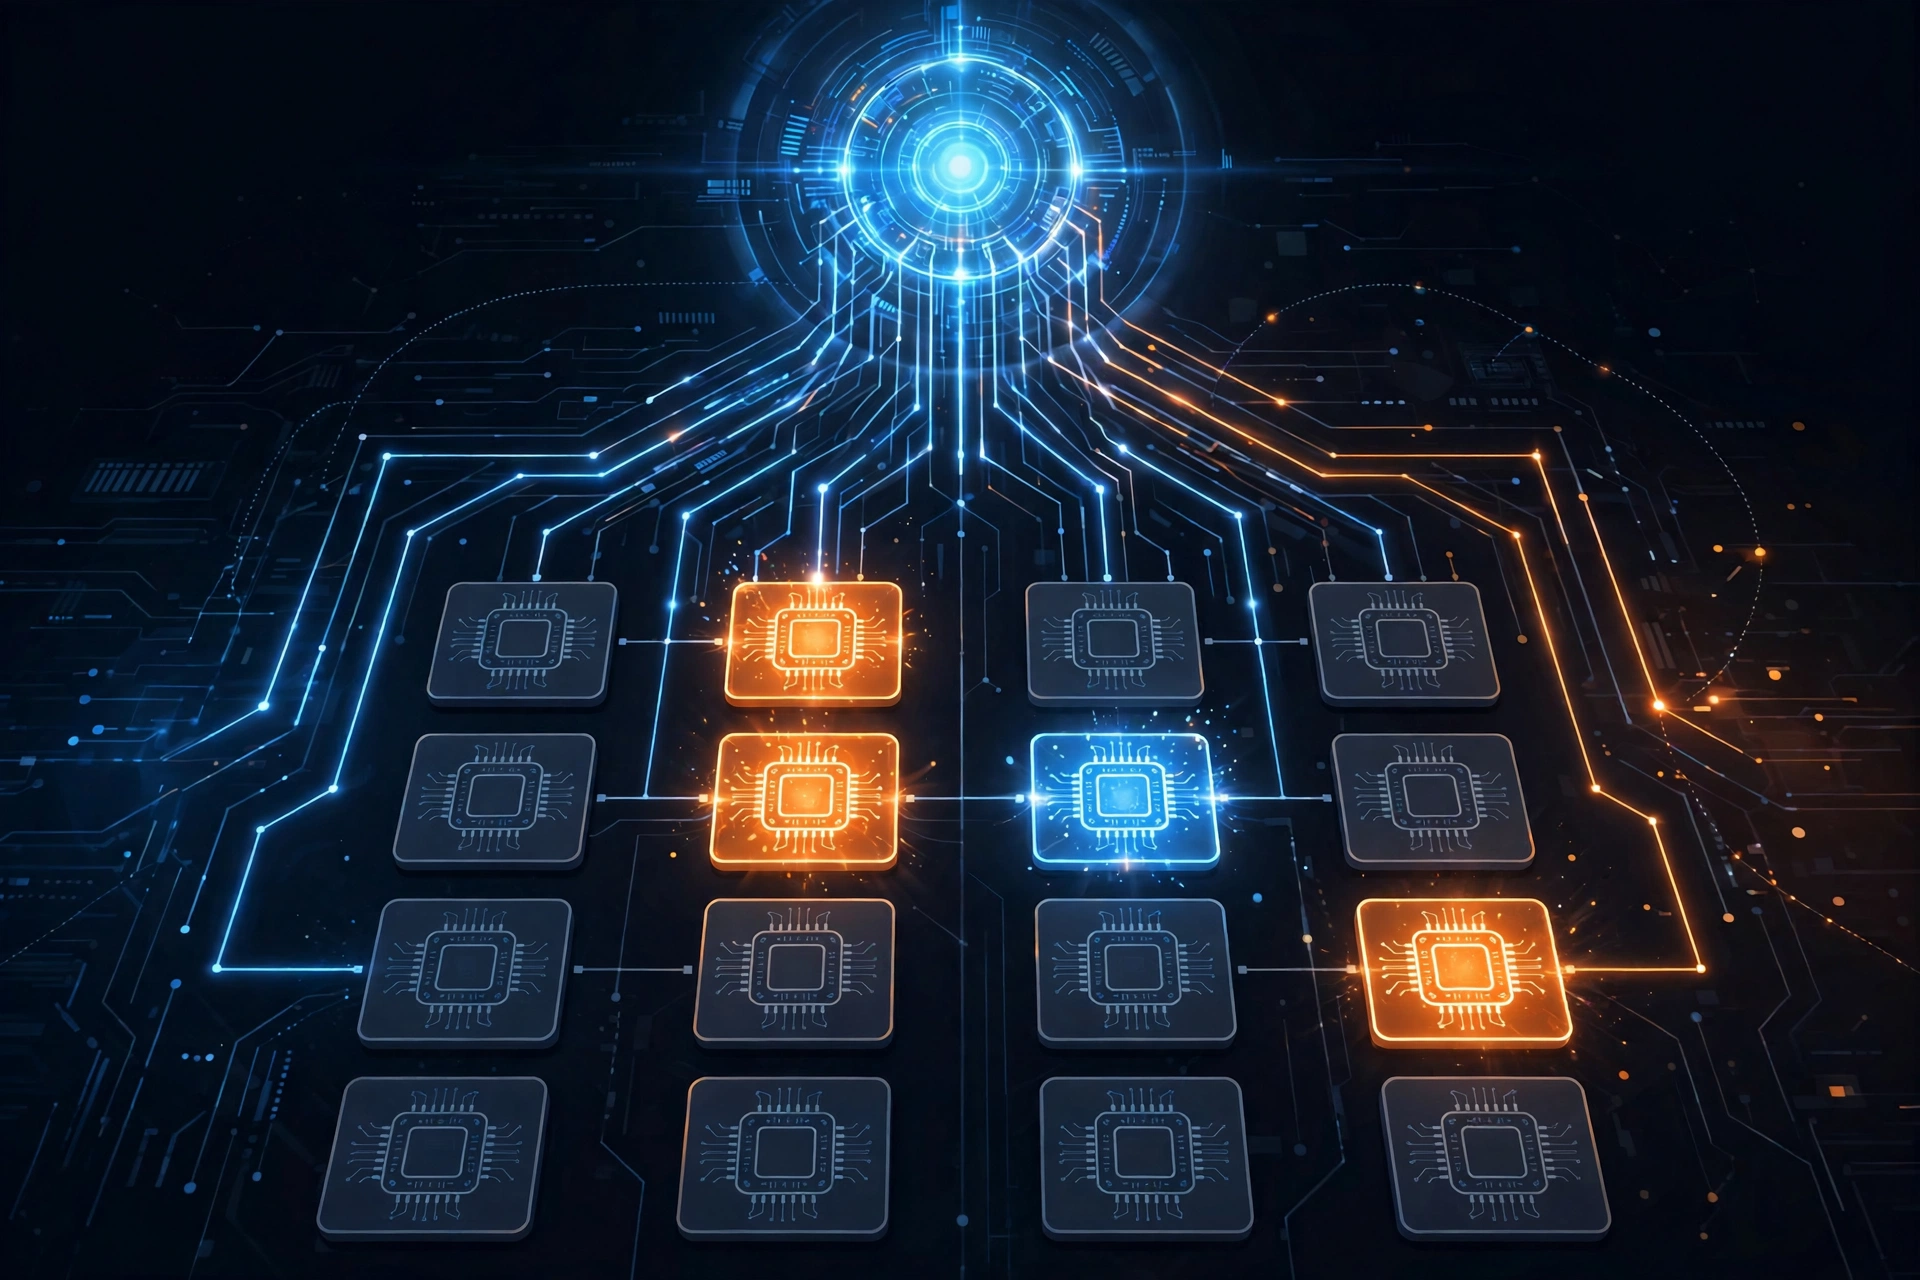
Large 4 is a Mixture-of-Experts (MoE) model. Of its roughly 1 trillion total parameters, only about 49 billion are active for any given token — 52 billion if you count the embedding and output layers. That is where the “A52B” in the official repository name comes from. The model routes each token through 4 of 128 experts, plus one shared expert, so most of the model’s knowledge sits idle on any single step while a small slice does the work.
It is natively multimodal, taking text and images as input and producing text, with a 1-million-token context window and support for more than 160 languages. A 1.6-billion-parameter vision encoder handles the image side. The architecture also uses multi-head latent attention with a DeepSeek-style sparse attention indexer, the same family of efficiency tricks that lets very large models stay practical at inference time.
The release ships in two official checkpoints on Hugging Face: an FP8 version at roughly 1,061 GB and a smaller NVFP4 version at about 610 GB aimed at Blackwell GPUs. Community builds in GGUF format shrink it further — the smallest is under 300 GB — but even those need serious hardware. Mistral’s own serving examples assume eight GPUs, and the company also offers the model through its API for teams that would rather not host it at all.
How the mixture-of-experts design works
The MoE trick is what makes a trillion-parameter model usable at all. A dense model of this size would activate every parameter for every token, which would be ruinously expensive to run. Large 4 activates only a small fraction per token, so its inference cost looks more like a 50-billion-parameter model even though its total knowledge is far larger.
That trade-off is not free. All 1 trillion parameters still have to sit in memory, which is why self-hosting needs a multi-GPU server rather than a single workstation. But for organizations that can afford the hardware, the payoff is a frontier-class model whose per-token cost stays manageable — and whose behavior they can inspect, modify, and control in ways a closed API never allows.
Mistral also added a three-mode reasoning switch — Low, Medium, and High — so developers can trade cost against precision per task. A quick classification job can run in Low mode; a hard coding problem can get the full High treatment. It is a small feature, but it reflects how these models are actually used in production: not every request deserves the same compute budget.
The benchmark claims — and why they need independent checks
Mistral’s reported results are strong, but every number below comes from the company itself, and independent replication was still pending when third-party write-ups appeared in early November. Treat them as claims, not confirmed facts.
On Cognition’s private FrontierCode 2.0 benchmark, which tests end-to-end code quality and whether a repository maintainer would merge an agent’s change, Mistral says Large 4 leads open-weight models with a score of 19.7%, just ahead of DeepSeek V4.1 Flash at 19.3%. On the Artificial Analysis Coding Agent Index it scores 48%, effectively tied with China’s GLM-5.3 while using 47% fewer tokens per task. Terminal-Bench 4.0 comes in at 41%, up 13 points from the preview while using 30% fewer output tokens, and BrowseComp at 84.5%.
The cybersecurity numbers cut both ways. Large 4 scores 51% on the Artificial Analysis Cyber Index, which measures a model’s ability to discover vulnerabilities in a codebase, reproduce and validate them, and patch them without breaking existing functionality. Its resistance to agent security attacks improved from 93.3% in the preview to 97.1% on the B3 Agent Security benchmark, and Mistral says the model refuses an average of 96.6% of malicious cyber requests. At the same time, the company is candid that the model could help with real attacks — once weights are public, no vendor can control how they are used. That tension is the central debate around every open-weight release, and Large 4, as the most capable one yet, sits right at its center.
Running it yourself: the real cost of self-hosting
Downloading the weights is free. Running them is not. The official FP8 checkpoint is about 1,061 GB of files, and Mistral’s serving recipes for vLLM and SGLang use a tensor-parallel size of eight — eight data-center GPUs. Hugging Face lists transformers and llama.cpp support from day one, and Mistral also publishes an optimized NVIDIA NIM container.
Community conversions make it slightly more approachable: a 2-bit MLX build of about 338 GB can fit on a single 512 GB Mac Studio, and a 3-bit build of about 459 GB also fits, while a 4-bit build at 590 GB needs two machines. But those builds depend on community code that was still awaiting review in early November, so the practical route for most teams is either a hosted API or a proper multi-GPU server.
For teams that skip self-hosting, the API is priced at $0.70 per million input tokens, $0.07 per million cached input tokens, and $2.10 per million output tokens. Microsoft Foundry is the first cloud platform to offer the model, and it is also listed on OpenRouter and Ollama’s cloud at the same rates.
The license: open weight, not open source
The legal terms matter as much as the technical ones. Large 4 is released under the Mistral Ecosystem Open-Weight License, which Mistral describes as a modified MIT license. Anyone may use, copy, modify, fine-tune, and commercialize the model and its derivatives for free — with one condition. Any business that operates a Model-as-a-Service offering must enter into a separate commercial license with Mistral before using the model commercially.
That distinction is why the release is called “open weight” rather than “open source.” The weights are downloadable and the license is permissive, but it is not an OSI-approved open-source license, and the model-as-a-service carve-out means cloud providers cannot simply resell Large 4 as a hosted service without a deal. For most developers and enterprises building their own products, the license is effectively free. For anyone planning to sell access to the model itself, the fine print matters.
Why this release matters for sovereign AI
The sovereignty angle is the thread running through the whole announcement. Mistral trained Large 4 from scratch on European infrastructure with what it calls clear lineage from inception to release, so a buyer can audit where the model came from and host it themselves. That pitch lands in a Europe that is increasingly wary of depending on US cloud providers for its most strategic technology, and it echoes across the industry: open-weight models are becoming the vehicle for countries and companies that want frontier AI without handing their data to someone else’s servers.
The open-weight field is also getting crowded at the top. Large 4 arrived weeks after Meta published its 816-billion-parameter Muse Spark Open, and it competes with strong open models from China such as GLM-5.3 and DeepSeek’s V4 line. What sets Large 4 apart is the combination: a Western lab, European training infrastructure, a permissive license, and benchmark claims that put it at or near the top of the open-weight class for coding.
Whether those claims hold up will be decided by independent evaluations in the coming weeks. What is already certain is that the most capable open-weight model from a European lab is now sitting on Hugging Face, free for anyone with enough hardware to run it. For developers, researchers, and any organization weighing the trade-off between a closed API and a model they can truly own, that is a genuine shift — not just another model release.
Related reading and sources
- Mistral’s official announcement: Mistral Large 4 (Le Chonk) is now open weight
- Download the weights on Hugging Face: Mistral-Large-4-1T-A52B
- Technology.org: Mistral Large 4 Goes Open Weight at 1T Parameters
- Tencent Hy4: open-source AI for defensive cybersecurity
- DeepSeek’s open-source coding agent
- NVIDIA Cosmos 3 Nano: open world models for simulation
- Enterprise AI spending hit $177 billion in 2026