
Every AI answer you get is really two jobs stitched together. First the system reads your prompt — that is prefill. Then it writes the reply, one token at a time — that is decode. For years, both jobs ran on the same chip. Cerebras now says they should not. In an announcement on November 17, 2026, the company said its disaggregated inference system is in production: GPUs handle the reading, and Cerebras’ wafer-scale chips handle the writing — and the combination delivers five times the throughput per megawatt of running everything on Cerebras hardware alone.
It is a simple idea with a big payoff, if the numbers hold up. And it is the latest sign that the AI inference market is splitting into specialized parts, with each kind of chip doing the job it is best at.
Prefill and Decode: Two Very Different Jobs
To understand why splitting inference makes sense, it helps to see how different the two stages are. Prefill processes the whole input prompt at once and builds the model’s internal state. It is a compute-heavy burst: lots of parallel math, done once per request. Decode is the opposite. It generates output tokens one at a time, feeding each new token back into the model to produce the next. It is sequential, repetitive, and limited less by raw compute than by memory bandwidth — how fast the chip can pull model weights and stored state out of memory for every single token.
Running both stages on the same hardware means compromising. A chip tuned for prefill’s parallel bursts is not ideal for decode’s memory-bound drip, and vice versa. Cerebras’ argument is that decode is where its wafer-scale design has an overwhelming advantage, so it should stop spending its capacity on prefill and hand that job to GPUs instead.
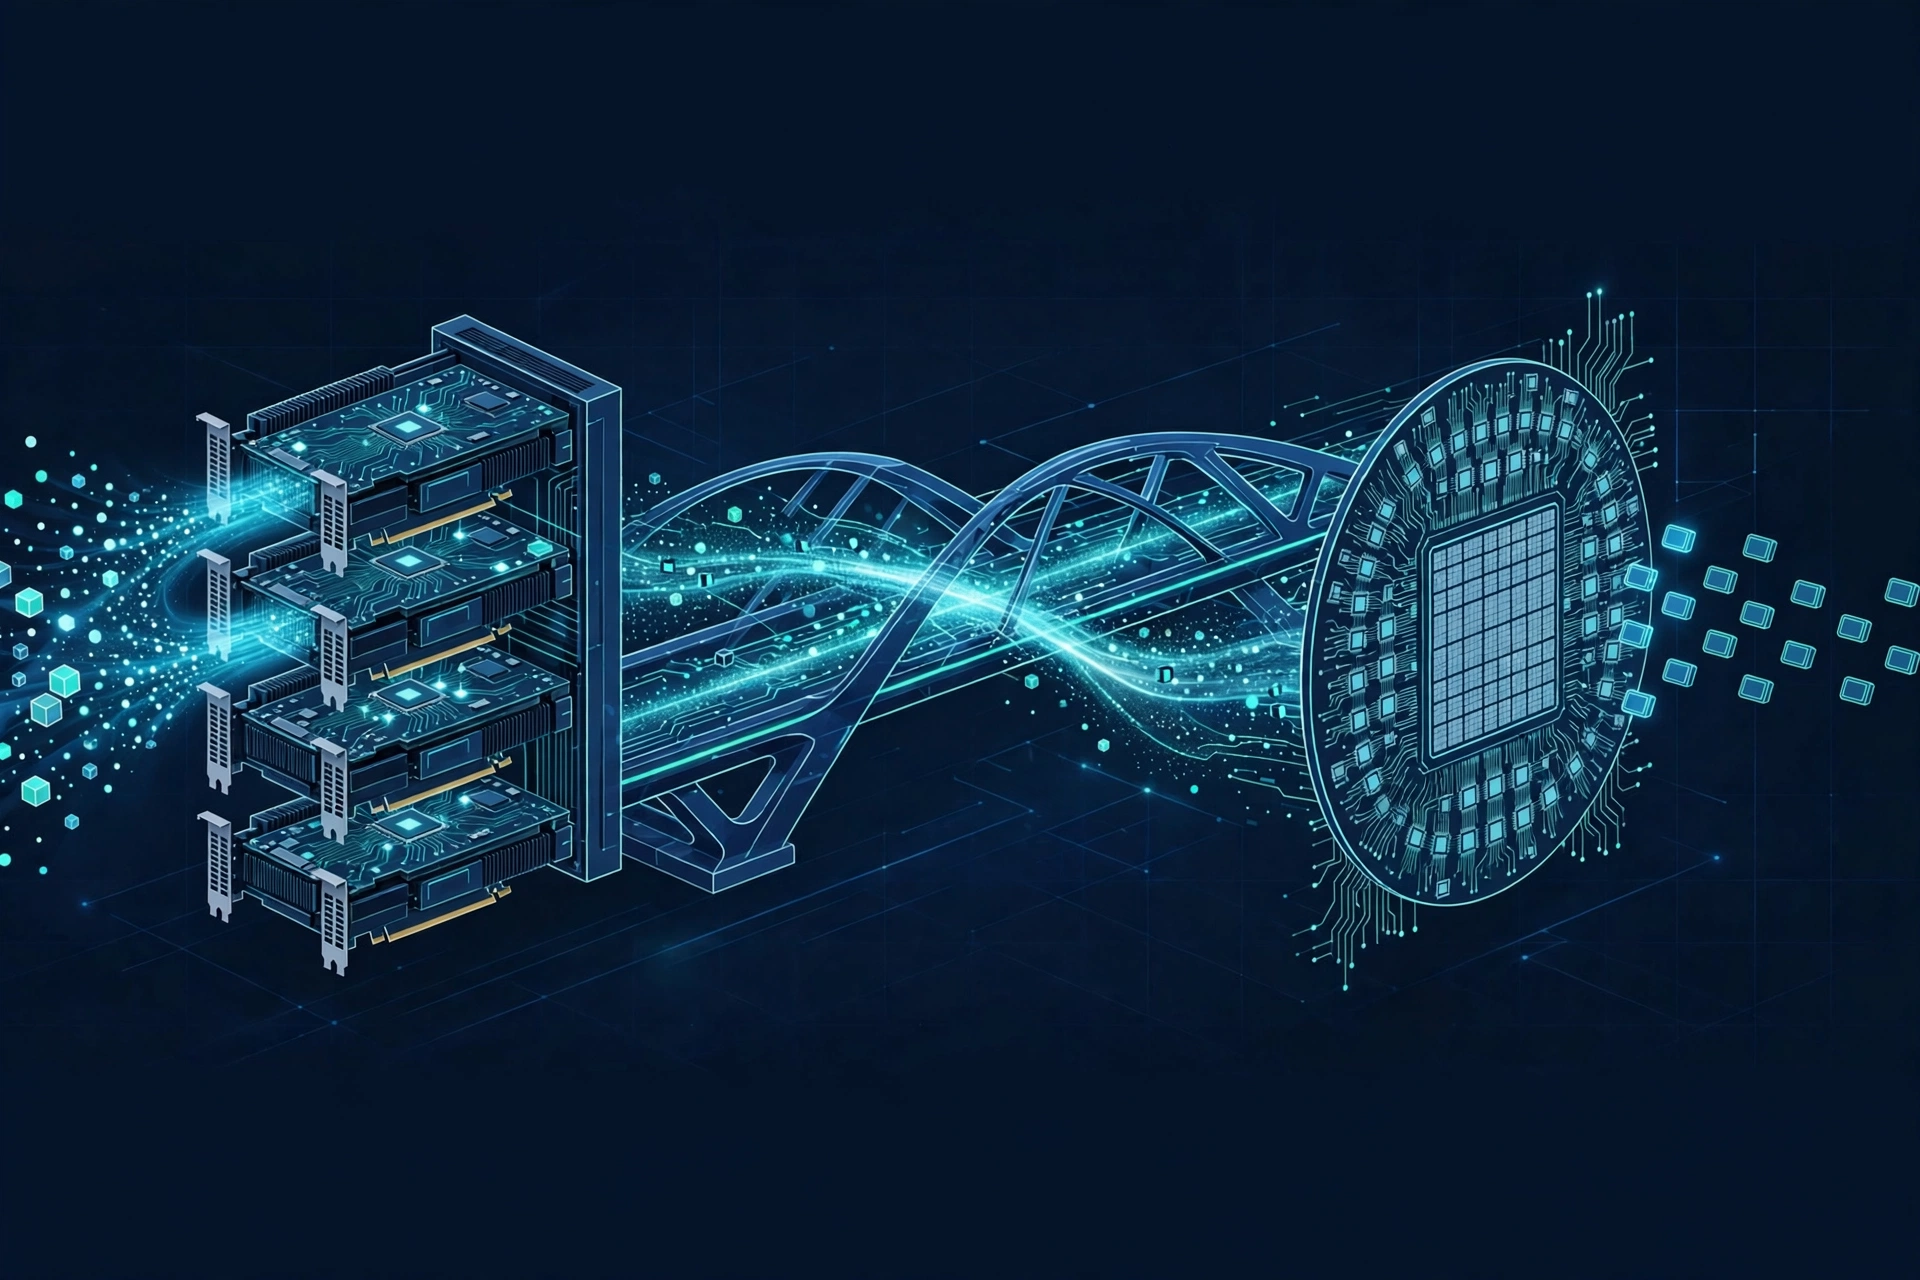
Why Cerebras Claims Decode Is Its Home Turf
Cerebras builds the Wafer Scale Engine, a chip the size of a dinner plate that keeps an entire AI model — or much of it — on the chip itself. The company says a single wafer-scale engine carries tens of gigabytes of SRAM and tens of petabytes per second of memory bandwidth, which it puts at 350 times the SRAM capacity and 5,400 times the memory bandwidth of a typical GB300 GPU. That matters because decode is a memory-bandwidth problem: the faster a chip can reach the model’s weights and the conversation’s stored state, the faster it can produce the next token — and the more requests it can serve at once.
By moving prefill to GPUs, Cerebras frees its systems to do only decode. The prompt work no longer competes with token generation for the same serving capacity, so the wafer-scale chips spend all of their time on the job they are built for. That is the whole logic of disaggregation: let each accelerator do what it does best, and connect them with software that makes the split invisible to the application.
The 5x Claim — and What It Actually Measures
The headline number is striking: five times the throughput per megawatt of a CS-3-only configuration, with no loss in token-generation speed. But the fine print matters. The measurement comes from a single shared GPT-OSS-120B endpoint on the Cerebras Inference Cloud, recorded on November 14, 2026, before and after disaggregation was switched on, with the old aggregated setup normalized to a 1x baseline. In other words, the 5x is a gain over Cerebras’ own previous configuration — not a comparison against a GPU-only system, and not an independent benchmark.
That is a fair caveat, not a dismissal. A fivefold efficiency gain on a production endpoint, at the same generation speed, is still a meaningful result if it reproduces across more models and workloads. It also echoes an earlier test: when Cerebras first explained disaggregated inference on October 1, 2026, it reported a 5x gain in early testing with the same wafer-scale footprint. The November announcement turns that early result into a production measurement — and adds a deployment package so infrastructure partners can run the same setup themselves.
What the company has not published is just as important: there are no absolute tokens-per-second figures and no power numbers behind the ratio, so the result cannot yet be checked against rivals’ systems. The honest reading is that disaggregation clearly helps Cerebras’ own cloud, and the wider industry will want to see the same gain on other models before treating 5x as a general rule.
How the Split Works in Practice
Cerebras built a software platform to make the split work. The full stack routes each request between a prefill pool and a decode pool, and manages replica capacity and health across both. The prefill engine can run open-source inference engines such as vLLM or SGLang, so teams do not have to abandon the tooling they already use. There is also a decode-only option: partners keep their own inference framework and prefill engine and use only Cerebras’ decode engine and its KV Portal, the component that hands the prompt’s processed state from the prefill side to the decode side.
The first partners getting early access are Amazon Web Services, Fireworks AI, Gimlet Labs and General Compute. Cerebras says it plans to deploy disaggregated inference broadly across hundreds of megawatts in its own inference cloud and in partner deployments by the end of 2027 — alongside the recently announced CS-4 and a planned 700MW of data center capacity.
What This Means for AI Developers
For developers and the companies serving AI models, the practical promise is cheaper fast tokens. Inference is the recurring cost of every AI product: every chatbot reply, every agent step, every code suggestion burns tokens, and the bill scales with usage. If splitting prefill and decode genuinely delivers more tokens per megawatt at the same speed, inference clouds can serve more users on the same power budget — and power, not silicon, is increasingly the scarce resource in AI data centers.
It also points to a more heterogeneous future. The old assumption was one accelerator for everything. The new picture is a mix: GPUs for prompt processing, wafer-scale chips for token generation, and different hardware for different stages of the same request. That same specialization is visible across the industry, from Microsoft’s Maia 200 inference chip built to make each token cheaper inside Azure, to AMD’s MI355X accelerators powering new Claude models, to startups like SiMa.ai building AI chips built to run many models on one device.
There is a business backdrop too. On its November 12 earnings call, Cerebras reported record Q3 2026 core revenue of $231 million, up 70% year over year, said the CS-4 is entering full production with double the CS-3’s performance and throughput, and said its next WSE-5 chip is back from the fab ahead of schedule with production expected in early summer 2027. Disaggregated inference is the software play that lets the company stretch its existing CS-3 capacity while the next generation ramps up.
The Bigger Picture: Inference Is Becoming a Team Sport
Cerebras’ announcement fits a pattern that is now hard to miss: the AI chip race has moved from training to inference, and from single-chip heroics to systems that combine different accelerators. Models keep getting more capable — from OpenAI’s GPT-6.2 Astra and Sol models to OpenAI’s GPT-5.2 — and every one of them has to be served to millions of users, millions of times a day. The companies that serve them cheapest, at the speed users expect, win the workload.
Splitting prefill and decode is one answer to that problem, and a 5x efficiency gain — even measured on one endpoint against Cerebras’ own baseline — is the kind of number that forces the rest of the industry to respond. Whether disaggregation becomes the default way inference is served, as Cerebras predicts, will depend on whether the gain holds across models, partners and power budgets. For now, the message is clear: in AI inference, the fastest chip may no longer be a single chip at all, but a team of them. Read the full details in the official Cerebras announcement, the Unite.AI report on the production launch, and this November 18 roundup covering the launch.

