On November 5, 2026, Supermicro announced a joint KV cache storage solution built with IBM and NVIDIA, aimed at one of the most expensive habits in modern AI: making GPUs redo work they have already done. Every time a model answers a long prompt, it first computes intermediate key-value states for the context it has been given. If that context is reused — a long document, a codebase, an ongoing conversation — those states can be stored and recalled instead of recomputed. The three companies say their new platform moves that stored context onto shared high-speed flash, and their joint testing claims up to 56 times faster time to first token on 130,000-token prompts.
The announcement matters because long-context work is now the default, not the exception. Coding assistants work across whole repositories, agents carry on multi-hour tasks, and retrieval systems feed models ever-larger piles of documents. All of that context has to live somewhere while the model works, and GPU memory alone cannot hold it. This launch is a bet that shared storage, properly networked, can become a real tier of AI memory rather than a slow fallback.
What the three companies actually announced
The solution combines four pieces: Supermicro Petascale all-flash storage servers running AMD EPYC 9005 Series processors, IBM Storage Scale software, NVIDIA’s Dynamo inference framework, and NVIDIA Spectrum-X Ethernet networking. Supermicro positions itself as the hardware and integration provider, IBM supplies the shared storage software layer, and NVIDIA contributes the inference software and the networking that ties the system together. The full announcement is in the official press release from Supermicro.
The platform falls under NVIDIA’s Inference Context Memory Storage Platform initiative, which NVIDIA introduced at CES 2026, and the three companies have been working on related efforts since mid-2025. Supermicro says its factory rack-integration and on-site deployment services can cut deployment time from weeks to days. No pricing was disclosed in the announcement.
Why the KV cache is the bottleneck for long-context AI
When a model processes a prompt, the first phase — prefill — turns the tokenized input into key-value states that the model then uses to generate its answer. Those states are the model’s working memory of the conversation so far. Recompute them from scratch on every request and you pay the full cost of reading a 130,000-token document again; store them and a follow-up question can start almost immediately.
The problem is capacity. Large codebases, documents, images and conversation histories create more key-value state than GPU memory and system DRAM can retain, so the cache gets evicted and the work gets repeated. A persistent, shared storage tier gives that state somewhere to live between requests, and makes it available to any GPU node in the cluster rather than only the one that computed it. That is the core idea behind this launch: treat context as data worth keeping, not as a byproduct to discard.
How the four pieces fit together
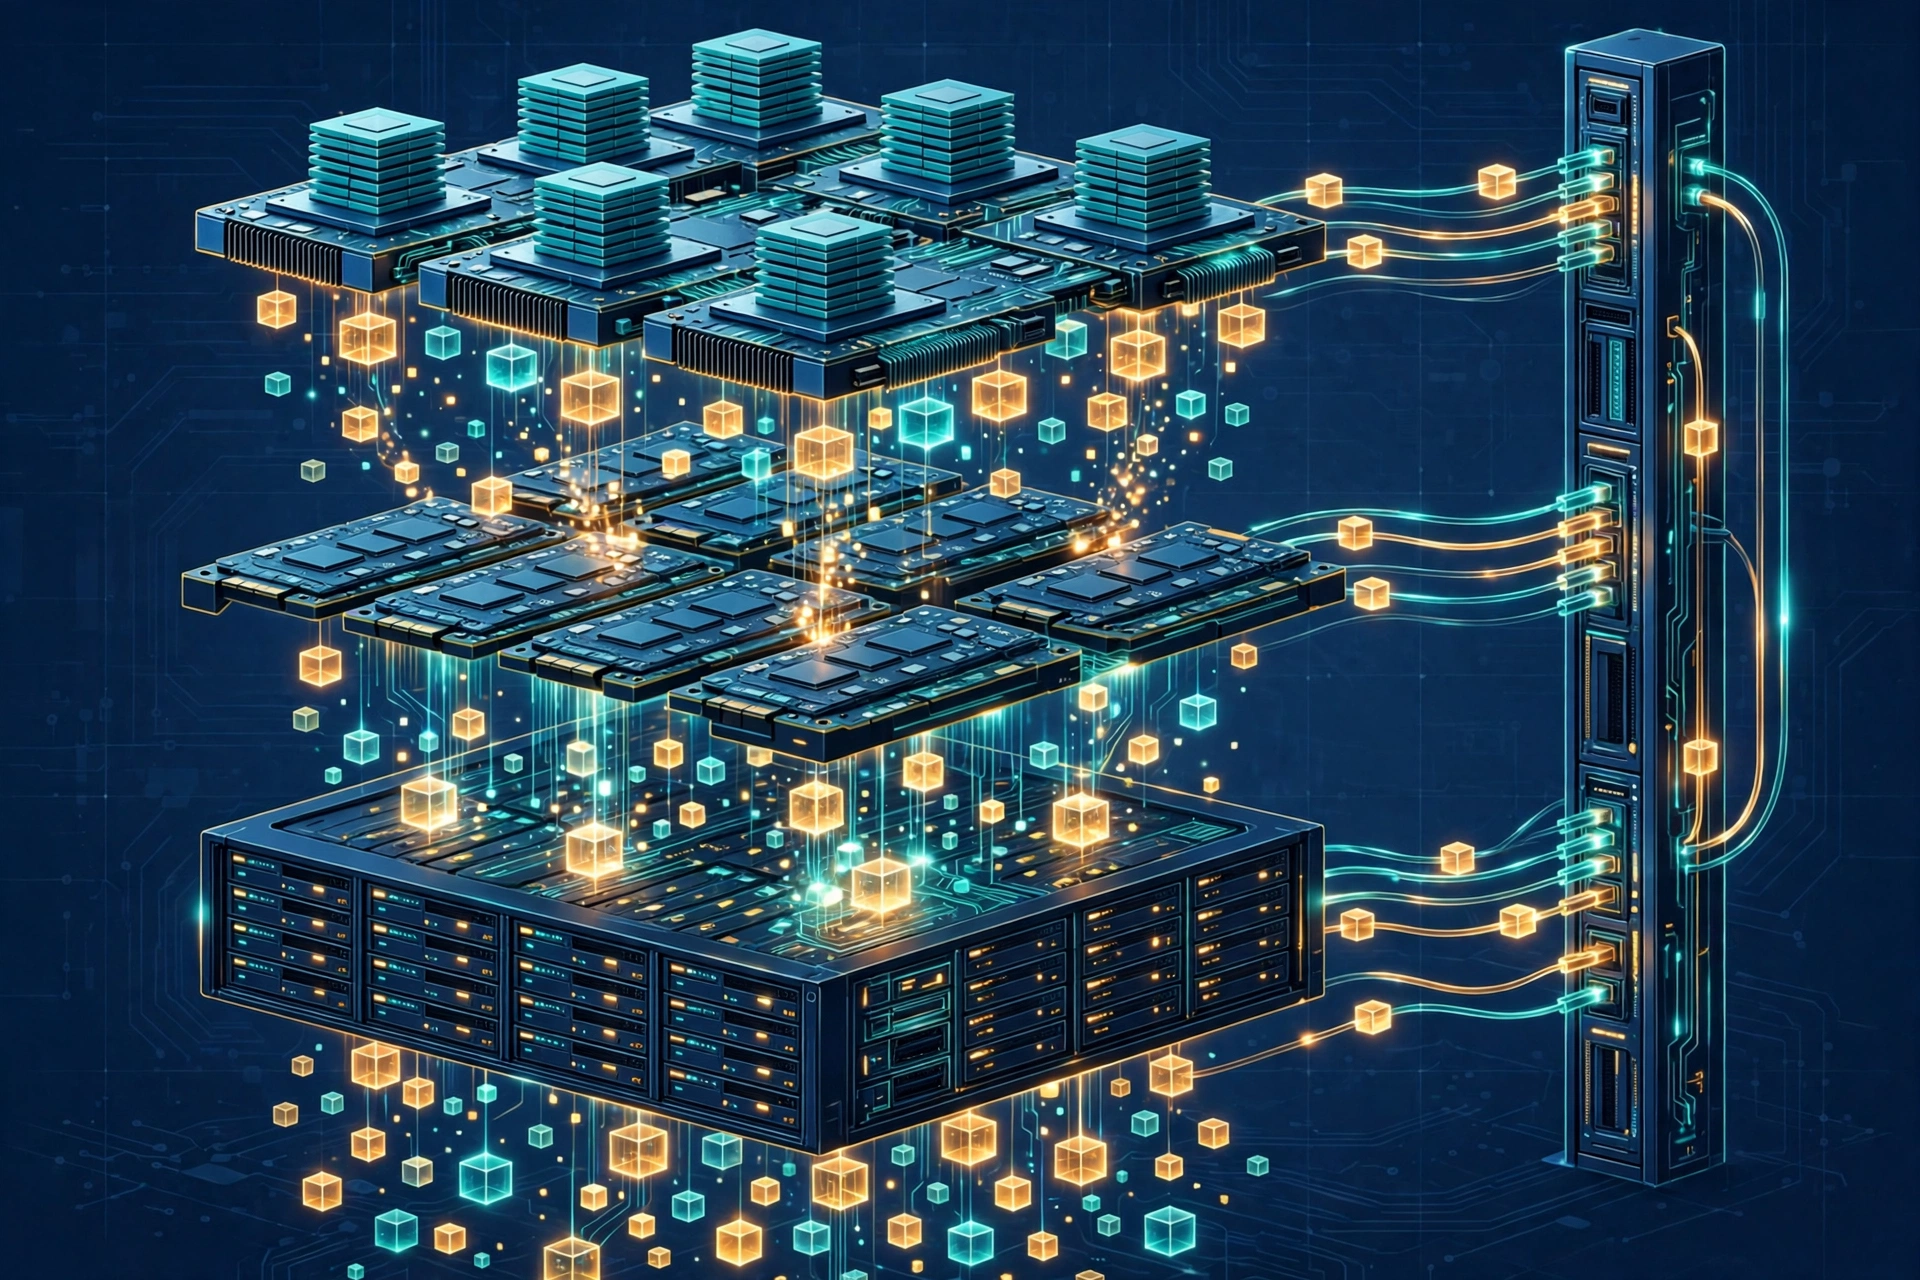
Each component has a distinct job. The Petascale servers provide the physical all-flash storage layer. IBM Storage Scale manages that storage as a shared, highly available tier with non-disruptive expansion, and its Erasure Coding Edition supplies the shared G4 tier in NVIDIA’s memory hierarchy — the layer below GPU memory and DRAM. NVIDIA Dynamo handles the inference side: it adds cache-aware routing, separates prefill from decode, and offloads cached blocks through its KV Block Manager and the NIXL transfer library. Spectrum-X Ethernet moves the data between the components fast enough for the cache to be useful rather than a bottleneck.
The sizing guidance in the supporting reference architecture scales from four storage nodes for a small proof of concept, through the eight-node configuration that was tested, to 16 or more nodes for large AI factories. Capacity, bandwidth, concurrency, model size and workload all affect the right design, and the companies stress that storage read headroom only helps if the client network can deliver it.
The benchmark numbers — and what they actually prove
The headline figure — up to 56x faster time to first token at 130,000-token prompts — comes from joint testing with a 120-billion-parameter language model, and it is detailed in IBM’s Redbook, Context without Limits: A High-Performance KV Cache Platform for Large-Scale AI Inference. That Redbook was published on June 5, 2026 and last updated on August 20, 2026, so the measurements underpin the launch rather than being a newly published November study.
The Redbook reports 32.14 seconds for GPU recomputation at 130,000 tokens versus 0.570 seconds using the storage-backed cache. A separate 200-request run used 28 concurrent connections and drew from 100 unique prompts representing 24 million tokens and 825 GB of KV cache data; throughput rose from 0.19 to 4.26 requests per second and total processing time fell from 1,048.56 to 46.94 seconds. The cache began empty, so that average includes a cold-start period while reuse built up. Under a noisy-neighbor test, four other clients generated 200 GB/s of competing network traffic; the cached system still sustained 3.6 requests per second and finished 200 requests in 55.56 seconds, an 18% throughput reduction from its clean-network result.
The test setup matters for reading those numbers honestly. All inference measurements came from one Supermicro GPU client node with four NVIDIA RTX PRO 6000 GPUs connected to an eight-node Petascale storage cluster, running Dynamo v0.9.0+, vLLM v0.14.1, NVIDIA AIPerf and the openai/gpt-oss-120b model, with the GPU-memory and system-DRAM cache tiers disabled to isolate the shared storage tier. Three Spectrum-X SN5600 switches formed the spine-leaf network; client-facing bandwidth reached up to 80 GB/s while the eight-node storage system achieved up to 315 GB/s of read throughput, making the client-side network the configuration’s constraint. The gains belong to that specific model, prompt mix, concurrency level and network — a useful proof of the architecture, not a guarantee for every workload. This is the same honest-reading discipline the industry needs elsewhere in the inference stack, where Together AI’s Polymorphic Inference also retunes serving systems automatically and reports its own strong but vendor-measured gains.
Who benefits first: coding assistants, agents and RAG
The companies name multi-turn and agentic applications, coding assistants, multimodal AI and long-context retrieval-augmented generation as the target workloads. The pattern is the same in each case: the same large context gets used again and again, so caching it pays off repeatedly. A coding assistant that re-reads a repository on every turn, an agent that keeps a session alive for hours, or a RAG system that repeatedly queries the same document set all fit that shape.
That puts the launch squarely in the middle of the agent-infrastructure race. Long-running agent runtimes such as Kimi Hosted Agents keep sessions, tools and history alive for hours, and they get slower and more expensive every time their context has to be rebuilt from scratch. Always-on agent products such as Snowflake’s always-on CoCo and CoWork Bots face the same pressure. And coding agents are generating more code than ever — OpenAI’s planned acquisition of Pierre Computer is a bet on the Git storage layer underneath that work — which means the context those agents carry is only getting bigger. Faster, cheaper context reuse helps all of them, provided the storage tier can keep up with the GPUs it serves.
What to watch next
Three things will decide whether this launch matters as much as its headline number suggests. First, customer results: the 56x figure is joint vendor testing on one model and one configuration, so independent benchmarks on real production workloads are the real test. Second, deployment economics: whether the savings in GPU time outweigh the cost of the Petascale hardware, IBM software and Spectrum-X networking for a given team. Third, the balance question the Redbook itself raises — whether storage capacity and client bandwidth are matched to actual context-reuse demand, since extra read headroom cannot improve inference if the client network cannot deliver it.
If those three hold, shared KV cache storage stops being a research curiosity and becomes a standard tier in AI infrastructure, sitting alongside GPU memory and DRAM. For a deeper technical read, see Unite.AI’s analysis of the launch and the IBM Redbook linked above.